Basics of Deep Learning and Foundation Models · Topic 2 of 3
CNN and RNN Architectures
Learn convolution, pooling, output size and parameter counts in CNNs, then recurrent networks, vanishing gradients and the gates of LSTM and GRU models.
- 6 min
- Includes a diagram
- CNN key ideas: local receptive fields and weight sharing; layers are convolution, activation, pooling, fully connected.
- Output size = (W - K + 2P) / S + 1; conv parameters = K x K x C_in x C_out + C_out.
- Pooling downsamples and has no learnable weights.
What it is
A convolutional neural network (CNN) is built for grid data such as images. Small filters slide over the input to detect local patterns like edges, then textures, then object parts.
A recurrent neural network (RNN) is built for sequences such as text, speech and time series. It reads one step at a time and carries a hidden state that remembers earlier steps.
How it works
Why convolution
A fully-connected layer on a 224 x 224 x 3 image would need over 150,000 weights per neuron. CNNs cut this with two ideas.
| Idea | Meaning |
|---|---|
| Local receptive field (local connectivity) | Each output looks only at a small patch, such as 3 x 3 |
| Weight sharing | The same filter weights are used at every position |
These give far fewer parameters, and a pattern is detected wherever it appears in the image.
CNN layers
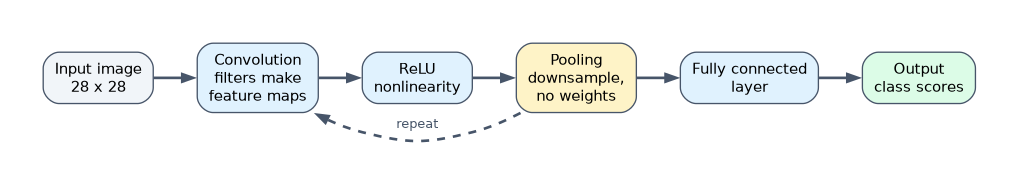
| Layer | Role |
|---|---|
| Convolutional layer | Filters slide over the input and produce feature maps; one map per filter |
| Activation (usually ReLU) | Adds nonlinearity |
| Pooling layer | Downsamples each feature map; max pooling keeps the largest value, average pooling the mean; no learned weights |
| Fully connected layer | Combines features into the final prediction |
Key settings of a convolution: kernel size K, stride S (step size) and padding P (zeros added around the edge).
Output size
For input width W: output = (W - K + 2P) / S + 1, rounded down.
| Input | K | P | S | Output |
|---|---|---|---|---|
| 32 | 5 | 0 | 1 | (32 - 5 + 0) / 1 + 1 = 28 |
| 32 | 5 | 2 | 1 | (32 - 5 + 4) / 1 + 1 = 32 ("same" size) |
| 224 | 7 | 3 | 2 | (224 - 7 + 6) / 2 + 1 = 111.5, rounded down to 111, + 1 = 112 |
| 28 (2 x 2 max pool) | 2 | 0 | 2 | (28 - 2) / 2 + 1 = 14 |
Parameter count
A conv layer has (K x K x input channels) weights per filter, plus one bias per filter. For 64 filters of 3 x 3 on an RGB input: 3 x 3 x 3 x 64 + 64 = 1,792 parameters, whatever the image size.
from torch import nn

conv = nn.Conv2d(in_channels=3, out_channels=64, kernel_size=3, padding=1)
pool = nn.MaxPool2d(kernel_size=2)       # stride defaults to kernel_size
print(sum(p.numel() for p in conv.parameters()))   # 1792
Classic CNNs
| Network | Known for |
|---|---|
| LeNet-5 | Early CNN for handwritten digits |
| AlexNet (2012) | Won ImageNet using ReLU, dropout and GPUs |
| VGG | Deep stacks of small 3 x 3 filters |
| ResNet | Residual (skip) connections that make very deep networks trainable |
Recurrent neural networks
At each time step t, the RNN combines the input x_t with the previous hidden state h_(t-1): h_t = tanh(W x_t + U h_(t-1) + b). The same weights are reused at every step.
RNNs are trained with backpropagation through time (BPTT), which unrolls the network across the steps. Over long sequences the gradient is multiplied many times, so it vanishes or explodes and plain RNNs forget early inputs.
LSTM and GRU
| Model | Gates | How it keeps long-term memory |
|---|---|---|
| LSTM (long short-term memory) | Forget gate, input gate, output gate | A separate cell state carries information; gates decide what to forget, add and output |
| GRU (gated recurrent unit) | Update gate, reset gate | Merges cell and hidden state; fewer parameters than LSTM, often similar accuracy |
Gates use sigmoid outputs between 0 and 1 to scale how much information passes, which eases the vanishing gradient problem.
A bidirectional RNN reads the sequence forward and backward, so each step sees both past and future context.
lstm = nn.LSTM(input_size=100, hidden_size=128, batch_first=True)Sequence task shapes
| Shape | Example |
|---|---|
| One to many | Image captioning |
| Many to one | Sentiment classification of a sentence |
| Many to many | Machine translation (encoder and decoder), tagging each word |
CNN versus RNN
| CNN | RNN, LSTM, GRU | |
|---|---|---|
| Data | Images, grids | Sequences, time series |
| Key idea | Local filters, weight sharing | Hidden state across time steps |
| Parallel training | Easy | Hard, steps run in order |
The sequential nature of RNNs is the main reason the Transformer replaced them for language.
A worked example
A 32 x 32 x 3 image passes a 5 x 5 convolution with 6 filters, no padding, stride 1. The output is 28 x 28 x 6, with 5 x 5 x 3 x 6 + 6 = 456 parameters.
A 2 x 2 max pool with stride 2 gives 14 x 14 x 6 and adds no parameters.
How the exam asks about this
- "An input of 32 x 32 passes a 3 x 3 convolution, padding 1, stride 1. What is the output size?" → 32 x 32, since (32 - 3 + 2) / 1 + 1 = 32.
- "Which LSTM gate decides what to discard from the cell state?" → The forget gate.
- "Which CNN layer downsamples feature maps and has no trainable parameters?" → The pooling layer.
What to remember for the exam
- CNN key ideas: local receptive fields and weight sharing; layers are convolution, activation, pooling, fully connected.
- Output size = (W - K + 2P) / S + 1; conv parameters = K x K x C_in x C_out + C_out.
- Pooling downsamples and has no learnable weights.
- Plain RNNs suffer vanishing gradients over long sequences; LSTM and GRU fix this with gates.
- LSTM has forget, input and output gates plus a cell state; GRU has update and reset gates.
CNN parameter count does not depend on the input image size. Only kernel size, input channels and filter count matter, because the weights are shared across positions.
Common mistakes
Thinking pooling learns features. Max and average pooling are fixed operations. They reduce size and add some translation invariance, with no weights.
Giving GRU three gates. GRU has two gates, update and reset. LSTM is the one with three gates and a cell state.
Thinking LSTM removes vanishing gradients entirely. Gates greatly reduce the problem, but very long sequences remain hard, which attention later addressed.
Check yourself
Why does weight sharing reduce CNN parameters?
The same filter is reused at every position, so the layer learns one small set of weights per filter instead of separate weights for every pixel.
What is backpropagation through time?
It is how RNNs are trained: the network is unrolled across time steps and gradients are passed back through each step with the chain rule.
Which is lighter, LSTM or GRU, and why?
GRU, because it has two gates instead of three and merges the cell and hidden state into one.
Topic 2 of 3 in Basics of Deep Learning and Foundation Models
Test yourself on Basics of Deep Learning and Foundation Models
The full Huawei HCIA-AI H13-311 question bank has 600 questions, with timed practice exams and an explanation for every answer.
This study guide is independent and is not affiliated with, endorsed by, or sponsored by Huawei. Vendor names, certification names and exam codes are trademarks of their respective owners and are used for identification only.