Using Spark Connect to Deploy Applications · Topic 1 of 1
Spark Connect and Deployment Modes
Spark Connect for the Databricks Spark exam: gRPC thin client, remote sessions, benefits and limits, plus client, cluster and local deployment modes.
- 5 min
- Includes a diagram
- Spark Connect is a decoupled client server architecture using gRPC and unresolved logical plans.
- The client is thin, and results come back as Arrow batches.
- Connect with
SparkSession.builder.remote("sc://host:15002"); the default port is 15002.
What it is
Spark Connect is a client server protocol that separates your application from the Spark driver. Your code runs as a thin client, and the Spark work runs on a Spark Connect server attached to the cluster. It was introduced in Apache Spark 3.4.
Deployment modes are a separate idea. They describe where the driver of a classic Spark application runs when you launch it.
How it works
The Spark Connect architecture
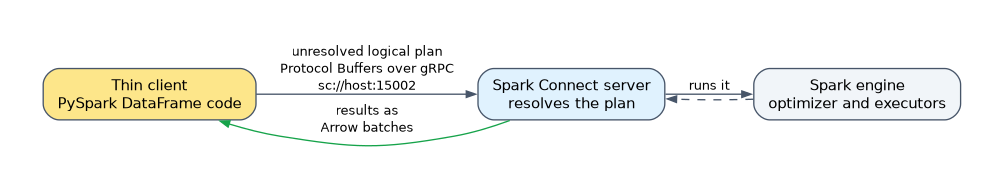 The client library turns DataFrame operations into an unresolved logical plan, encoded with Protocol Buffers, and sends it over gRPC. The server resolves the plan into a Spark logical plan and runs it with the normal engine, so all optimizations still apply. Results stream back to the client as Apache Arrow encoded batches.
You connect with the remote() builder method. The default server port is 15002.
from pyspark.sql import SparkSession
spark = (SparkSession.builder
    .remote("sc://localhost:15002").getOrCreate())
spark.range(5).show()
The SPARK_REMOTE environment variable can supply the same connection string without code changes.
Features and benefits
| Feature | What it means |
|---|---|
| Decoupled client and server | The client runs in its own process, away from the driver |
| Stability | A client that uses a lot of memory cannot crash the driver |
| Upgradability | The server can be upgraded without changing client applications |
| Remote and embedded use | A thin client can run in an IDE, a notebook or an application server |
| Debuggability | Use IDE debuggers and the application's own logging |
| Many languages | Any language can build a client that speaks the protocol |
Databricks Connect is built on Spark Connect, which lets you run local code against a Databricks cluster.
Limits of Spark Connect
The client is not in the same process as the driver, so it has no direct JVM access. The RDD API and SparkContext are not available, and neither are other APIs that depend on a JVM object such as df._jdf. You work with sessions, DataFrames, SQL and functions. Most of the PySpark DataFrame API is supported.
Deployment modes
A deployment mode sets where the driver runs. You choose it with the master URL and the --deploy-mode option of spark-submit.
| Mode | Where the driver runs | Typical use |
|---|---|---|
| Client | In the process that submitted the application | Interactive shells, notebooks, submitting from a machine near the workers |
| Cluster | On a node inside the cluster | Production jobs submitted from a distant machine |
| Local | One JVM on one machine, driver and executors together | Development and tests |
Client mode is the default for spark-submit. In client mode, console input and output stay attached to the submitting machine. In cluster mode the submitting machine can disconnect, and network traffic between driver and executors stays inside the cluster.
Local mode is selected with --master local. local[4] uses four threads and local[*] uses as many threads as logical cores. Plain local uses a single thread, so there is no parallelism.
spark-submit --master yarn --deploy-mode cluster app.pyCluster mode is available with cluster managers such as YARN and Kubernetes. A standalone cluster does not support cluster mode for Python applications.
How the exam asks about this
- "Which feature lets a client application run in an IDE while Spark runs on a remote cluster?" Spark Connect.
- "What protocol does the Spark Connect client use to send plans?" gRPC, carrying unresolved logical plans.
- "You need the driver to survive the laptop that submitted the job closing." Use cluster mode.
What to remember for the exam
- Spark Connect is a decoupled client server architecture using gRPC and unresolved logical plans.
- The client is thin, and results come back as Arrow batches.
- Connect with
SparkSession.builder.remote("sc://host:15002"); the default port is 15002. - Spark Connect has no RDD API and no SparkContext access.
- Client mode puts the driver on the submitting machine; cluster mode puts it inside the cluster; local mode runs everything in one JVM.
local[*]uses all logical cores; plainlocaluses one thread.
Do not assume code that uses spark.sparkContext or RDDs runs over Spark Connect. Those APIs fail, so rewrite them with DataFrame operations.
Common mistakes
Calling Spark Connect a new execution engine. It does not change how queries run. It changes where the client lives and how plans reach the server.
Mixing up client mode and Spark Connect. Client deploy mode still runs a full driver in the submitting process. Spark Connect has no driver in the client at all, only a thin client.
Treating local mode as distributed. Local mode runs in one JVM. It is for development, and local without a thread count is not parallel.
Check yourself
What does a Spark Connect client send to the server?
An unresolved logical plan built from DataFrame operations, encoded with Protocol Buffers and sent over gRPC.
Which two Spark APIs are unavailable through Spark Connect?
The RDD API and SparkContext, because the protocol is built on logical plans and the client has no JVM access.
In which deploy mode does the driver run on the machine that ran spark-submit?
Client mode; in cluster mode the driver runs on a node inside the cluster.
Topic 1 of 1 in Using Spark Connect to Deploy Applications
Test yourself on Using Spark Connect to Deploy Applications
The full Databricks Associate Developer for Apache Spark question bank has 600 questions, with timed practice exams and an explanation for every answer.
This study guide is independent and is not affiliated with, endorsed by, or sponsored by Databricks. Vendor names, certification names and exam codes are trademarks of their respective owners and are used for identification only.