Data Engineering · Topic 7 of 16
Snowflake Ecosystem Tools and Connectors for Kafka, Spark and Python
Know how the Snowflake Connector for Kafka, the Spark connector and the Python connector work, what each is for and how they authenticate and move data.
- 5 min
- Includes a diagram
- Kafka connector:
RECORD_METADATAandRECORD_CONTENTcolumns, key pair authentication, classic methods Snowpipe (default) or Snowpipe Streaming; v4 uses Snowpipe Streaming only. - Spark connector: DataFrame source and sink, query pushdown, bulk transfer through a stage.
- Python connector: DB-API 2.0,
fetch_pandas_all,write_pandas, many authentication options.
What it is
Snowflake's ecosystem is a set of clients that talk to the same service. Connectors are ready made integrations for a platform such as Kafka, Spark or Python. Drivers (JDBC, ODBC) are lower level database interfaces. Command line tools (SnowSQL, Snowflake CLI) and Snowpark run SQL and code. All of them sign in to an account, run work on a virtual warehouse or serverless compute, and move data over HTTPS.
The exam asks which tool belongs to which scenario and how it interacts with Snowflake: through a stage, through the SQL API, or by pushing work down to Snowflake.
How it works
Snowflake Connector for Kafka
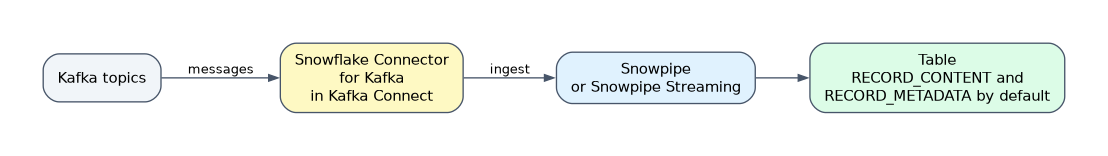 The Kafka connector runs inside Kafka Connect (Apache Kafka or Confluent Platform) and reads topics into Snowflake tables. By default each topic maps to one table, and you can map several topics to a table or give a topic a custom table name.
Each loaded row has two VARIANT columns: RECORD_METADATA (topic, partition, offset, timestamp and key) and RECORD_CONTENT (the message).
The classic connector (v3 and earlier) offers two ingestion methods. The v4 connector, which Snowflake recommends for new implementations, uses only the high performance Snowpipe Streaming architecture through pipe objects.
| Ingestion method (classic connector) | How it loads | Latency | Notes |
|---|---|---|---|
| Snowpipe (the default) | Buffers records into files on an internal stage, a pipe loads them | Seconds to minutes | Connector creates a stage and pipes per partition |
| Snowpipe Streaming | Writes rows over channels with no files | Lower, seconds | Set snowflake.ingestion.method to SNOWPIPE_STREAMING |
Authentication uses key pair authentication. The connector needs a role with the privileges to create tables, stages and pipes (or to insert into existing tables for streaming). Schema evolution can be enabled so new fields in messages become new columns.
Kafka plus "lowest latency" points to the connector with Snowpipe Streaming. Kafka plus "default setup" on the classic connector points to the Snowpipe method.
The connector tracks Kafka offsets so messages are neither duplicated nor silently dropped in normal operation: with Snowpipe it uses file names that encode topic, partition and offsets, and with streaming it uses channel offset tokens. Snowflake documents exactly once delivery for the v4 connector; with the classic Snowpipe method rare duplicates are possible, and two connector instances reading the same partitions can insert duplicate rows.
Snowflake Connector for Spark
The Spark connector makes Snowflake a data source and sink for Spark DataFrames. In Spark you use format("net.snowflake.spark.snowflake") with options such as sfURL, sfUser, sfDatabase, sfSchema, sfWarehouse and either dbtable or query.
Two interactions matter.
- Reading: the connector can push down filters, projections, joins and aggregations to Snowflake as SQL, so Snowflake does the heavy work and Spark receives smaller results.
- Data transfer: it moves large data through an internal or external stage (the connector can use a temporary stage with
COPY INTOfor writes and unload for reads), not row by row over JDBC.
The Spark connector is the right choice when Spark is already the compute engine and the pipeline must read from or write to Snowflake. If the work can run in Snowflake itself, Snowpark avoids moving data at all.
Snowflake Connector for Python
The Python connector is a pure Python package that implements the DB-API 2.0 standard. It lets any Python program connect, run SQL and fetch results.
import snowflake.connector

conn = snowflake.connector.connect(
    account="myorg-myaccount",
    user="loader",
    private_key_file="rsa_key.p8",
    warehouse="etl_wh",
    database="sales",
)
cur = conn.cursor()
cur.execute("SELECT * FROM orders LIMIT 10")
df = cur.fetch_pandas_all()
Useful pieces to recognize:
fetch_pandas_all()andfetch_pandas_batches()return results as pandas DataFrames, using Apache Arrow for speed.write_pandas()loads a DataFrame into a table by writing Parquet files to a temporary stage and running COPY.execute_asyncruns a statement without waiting; you check the query ID later.- Authentication options include password, key pair, OAuth, SSO through an external browser and multi factor authentication.
- The
snowflake-sqlalchemypackage builds on it for SQLAlchemy.
The Python connector sends SQL; it does not run Python inside Snowflake. For Python that runs next to the data, use Snowpark.
Common mistakes
Choosing Snowpipe method when seconds matter. The classic Kafka connector default writes files and a pipe loads them. Streaming is the low latency mode.
Using the Spark connector to move data you could process in Snowflake. Data crosses the network twice when a pushdown query or Snowpark would do.
Expecting the Python connector to run Python in Snowflake. It is a client; Snowpark and Python UDFs run in Snowflake.
Forgetting key pair setup for Kafka. The connector authenticates with a private key, so the public key must be assigned to the Snowflake user.
What to remember for the exam
- Kafka connector:
RECORD_METADATAandRECORD_CONTENTcolumns, key pair authentication, classic methods Snowpipe (default) or Snowpipe Streaming; v4 uses Snowpipe Streaming only. - Spark connector: DataFrame source and sink, query pushdown, bulk transfer through a stage.
- Python connector: DB-API 2.0,
fetch_pandas_all,write_pandas, many authentication options. - Connectors run on the client side; compute is the warehouse or serverless service.
- If processing can stay inside Snowflake, Snowpark beats moving data to Spark.
Check yourself
Which Kafka connector setting gives the lowest latency?
Ingestion method
SNOWPIPE_STREAMING, which writes rows through channels instead of files.What does Spark query pushdown do?
It turns filters, joins and aggregations into SQL that Snowflake runs, so Spark gets only the reduced result.
Which Python connector call loads a pandas DataFrame into a table?
write_pandas, which stages Parquet files and runs COPY.
Topic 7 of 16 in Data Engineering
Test yourself on Data Engineering
The full Snowflake ARA-C01 question bank has 687 questions, with timed practice exams and an explanation for every answer.
This study guide is independent and is not affiliated with, endorsed by, or sponsored by Snowflake. Vendor names, certification names and exam codes are trademarks of their respective owners and are used for identification only.