Implement an instrumentation strategy · Topic 2 of 2
Analyzing Metrics, Logs and Traces
AZ-400 telemetry analysis: CPU, memory, disk and network indicators, Application Insights views, distributed tracing and basic KQL queries.
- 6 min
- Includes a diagram
- Guest memory and disk counters need the Azure Monitor Agent or VM insights.
- Application Map shows dependencies. Performance, Failures and Live Metrics help during releases. Usage views cover users, funnels and retention.
- Distributed tracing relies on a trace identifier (
operation_Id, W3Ctraceparent) and an end-to-end transaction view.
What it is
Collecting telemetry is only useful if you can answer questions with it. Is the service healthy? What got slower after the deployment? Which dependency is failing? This topic covers reading infrastructure performance indicators, analyzing usage and application performance, following a request across services with distributed tracing, and writing basic Kusto Query Language (KQL) queries.
How it works
Infrastructure performance indicators
| Indicator | What to look at |
|---|---|
| CPU | Sustained high percentage suggests the instance is saturated. Look at average and peak |
| Memory | Available memory trending down can mean a leak. Guest memory needs the Azure Monitor Agent or VM insights, because platform metrics do not include it for VMs |
| Disk | Read and write operations, throughput, queue depth and free space |
| Network | Bytes in and out, connection failures, latency |
Use Metrics Explorer to chart a metric with an aggregation (average, min, max, sum, count), split by a dimension (instance, region) and filter. Dynamic thresholds learn normal patterns. VM insights and Container insights show performance and health at a glance, including node pressure and pod restarts in AKS. The "four golden signals" give a useful checklist: latency, traffic, errors and saturation.
Usage and application performance
Application Insights gives views for both.
| View | Answers |
|---|---|
| Performance | Slowest operations and dependencies, response time percentiles |
| Failures | Failed requests, exceptions and failed dependency calls |
| Application Map | Components, the calls between them, and where failures occur |
| Live Metrics | Real time rate, failures and server health during a deployment |
| Usage (Users, Sessions, Events) | Who uses the app, how often, which features |
| Funnels, Retention, User flows, Cohorts | How users move through steps, return over time or leave |
| Availability | Results of synthetic tests from several locations |
Compare the before and after of a release using release annotations, and judge against a baseline, such as the same time last week. Look at percentiles (for example the 95th) as well as averages, because averages hide slow tails.
Distributed tracing
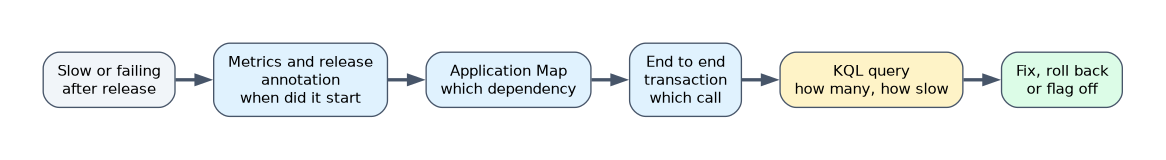 In a system of many services, one user request touches several of them. Distributed tracing follows that request end to end.
- Each request carries a trace identifier, passed between services in the W3C Trace Context header (
traceparent). Application Insights stores it asoperation_Id, with parent and child relationships between operations. - The end-to-end transaction view shows a request as a timeline: which service, which dependency call, how long each took and where an exception happened.
- Give each component a distinct cloud role name so the Application Map and traces show readable service names.
- Telemetry is correlated automatically by the SDKs or the OpenTelemetry distro for supported libraries. Custom code that creates its own threads or uses unsupported protocols may need manual propagation.
- Sampling keeps a share of telemetry. Adaptive sampling keeps related items together so traces stay whole.
Kusto Query Language (KQL)
KQL queries read from a table and pass the result through a series of operators separated by the pipe character.
| Operator | Purpose |
|---|---|
where | Filter rows |
project | Choose columns |
extend | Add a calculated column |
summarize ... by | Aggregate (count(), avg(), percentile(), countif()) |
bin() | Group a time into buckets |
order by / top | Sort or take the highest |
take | Return a sample of rows |
join, union | Combine tables |
render | Chart the result (timechart, barchart) |
ago() | A time relative to now |
Failed request rate over time (in the Application Insights Logs view, tables are named requests, dependencies, exceptions, traces):
requests
| where timestamp > ago(1h)
| summarize failed = countif(success == false), total = count() by bin(timestamp, 5m)
| extend failureRate = 100.0 * failed / total
| render timechart
Slowest operations by 95th percentile:
requests
| where timestamp > ago(24h)
| summarize p95 = percentile(duration, 95), calls = count() by name
| top 10 by p95 desc
CPU by computer from the Perf table in a Log Analytics workspace:
Perf
| where ObjectName == "Processor" and CounterName == "% Processor Time" and InstanceName == "_Total"
| summarize avg(CounterValue) by Computer, bin(TimeGenerated, 5m)
Follow one request across services:
union requests, dependencies, exceptions
| where operation_Id == "<trace id>"
| order by timestamp asc
In a Log Analytics workspace the same Application Insights data is in tables named AppRequests, AppDependencies, AppExceptions and AppTraces, and the time column is TimeGenerated. Prefer has over contains for string matching, because it is faster, and filter by time first.
From analysis to action
- Save a query as a log alert so it runs on a schedule and notifies an action group.
- Pin charts to a dashboard or a workbook for a shared view.
- Use findings to adjust autoscale, size VMs, tune queries or fix a slow dependency.
- Feed results back into the pipeline: gates that check alerts, and a post deployment verification that queries error rate.
A worked scenario
After a Tuesday release, support reports that checkout is slow. The engineer opens Application Insights, sees from the release annotation that response time doubled right after deployment, and the Application Map shows a red dependency on the payment service. In the end-to-end transaction view, one call to the payment API takes six seconds. A KQL summarize percentile(duration, 95) by name confirms it affects only that operation. The team rolls back the payment change and saves the query as an alert.
What to remember for the exam
- Guest memory and disk counters need the Azure Monitor Agent or VM insights.
- Application Map shows dependencies. Performance, Failures and Live Metrics help during releases. Usage views cover users, funnels and retention.
- Distributed tracing relies on a trace identifier (
operation_Id, W3Ctraceparent) and an end-to-end transaction view. - KQL:
where,summarize ... by bin(timestamp, 5m),percentile(),render timechart. - Workspace tables use
Appprefixed names such asAppRequests.
When a KQL question asks for "per 5 minutes", the answer contains summarize ... by bin(timestamp, 5m).
How the exam asks about this
- "Find which dependency makes requests slow." Application Map or the end-to-end transaction view.
- "Count failed requests per 5 minutes and chart it." A KQL query with
summarizeandbin. - "Follow a single request across microservices." Distributed tracing with the operation ID.
- "See who uses a feature and where they drop off." Usage analysis with funnels.
Common mistakes
Looking only at averages. Use percentiles to see slow tails.
Missing guest metrics. Platform metrics for a VM exclude memory and disk space inside the guest.
Forgetting the time filter. Queries without one scan too much data.
Mixing table names. Application Insights Logs uses requests. A workspace uses AppRequests.
Check yourself
Which KQL operator groups time into buckets of a chosen size?
bin.
Which Application Insights field links the telemetry items of one distributed request?
operation_Id.
Which Application Insights view shows the components of a system and the calls between them?
Application Map.
Topic 2 of 2 in Implement an instrumentation strategy
Test yourself on Implement an instrumentation strategy
The full Microsoft AZ-400 question bank has 766 questions, with timed practice exams and an explanation for every answer.
This study guide is independent and is not affiliated with, endorsed by, or sponsored by Microsoft. Vendor names, certification names and exam codes are trademarks of their respective owners and are used for identification only.