Design business continuity solutions · Topic 3 of 4
High Availability for Compute
AZ-305 compute availability: availability zones, availability sets, scale sets, load balancer zone redundancy, platform service resilience and SLA targets.
- 6 min
- Includes a diagram
- SLAs: single VM on premium disks 99.9, availability set 99.95, availability zones 99.99.
- A zonal VM alone does not survive a zone failure. Use instances in several zones.
- Flexible orchestration is recommended for new scale sets. The mode cannot be changed later.
What it is
High availability (HA) keeps a service running when a component fails, without human action. In Azure, HA is built from redundancy at several levels: fault domains within a datacenter, availability zones across datacenters in a region and regions across geography. Choosing the level sets the SLA and the cost.
How it works
Levels of redundancy
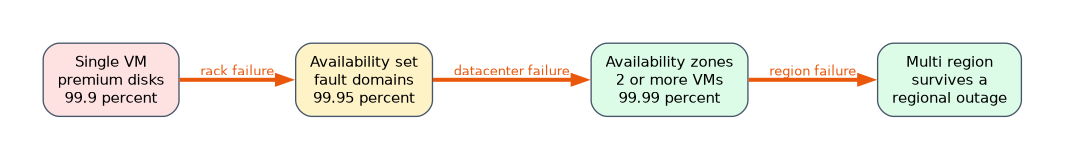
| Level | Protects against | SLA guidance |
|---|---|---|
| Single VM on premium SSD or Ultra disks | Little. Planned maintenance may reboot it | 99.9 percent |
| Availability set (2 or more VMs across fault and update domains) | Rack and hardware failure and maintenance within one datacenter | 99.95 percent |
| Availability zones (2 or more VMs across zones) | A datacenter failure in the region | 99.99 percent |
| Multi region | A regional outage | Depends on design and the traffic manager |
A zonal VM is pinned to one zone and is not resilient to that zone failing. For zone resilience you need instances in several zones behind a zone redundant front end. An availability set and a zone cannot both be used for one VM, but scale sets use zones directly.
Virtual machine scale sets
Virtual Machine Scale Sets (VMSS) run a group of VMs that scale with demand.
| Mode | Use |
|---|---|
| Flexible orchestration | Recommended for new workloads. Mix VM sizes and types, spread across zones and fault domains, and manage VMs individually |
| Uniform | Large sets of identical, stateless instances |
Spread a scale set over three zones with zone balancing, set a minimum instance count, and add autoscale rules plus automatic instance repairs driven by health probes. Orchestration mode cannot be changed after creation. A flexible scale set across three zones behind a Standard load balancer is the usual answer for a stateless app that needs 99.99 percent and datacenter failure survival with minimal application change.
Load balancing for availability
| Service | HA behaviour |
|---|---|
| Standard Load Balancer | Zone redundant frontend survives a zone failure. Health probes remove unhealthy instances. The Basic SKU is retired |
| Application Gateway v2 | Zone redundant, autoscaling Layer 7 |
| Azure Front Door | Global, fails over between regional origins |
| Traffic Manager | DNS based failover between regions |
| NAT Gateway | Zone resilience through zonal or the zone redundant StandardV2 SKU |
Place all tiers in zones and make each tier's front end zone redundant. For network virtual appliances that have no failover of their own, use an internal Standard Load Balancer with HA ports and a zone redundant frontend as the next hop. For SAP style workloads that need very low latency between app and database, use proximity placement groups inside each zone.
Platform services
| Service | Availability design |
|---|---|
| App Service | Zone redundancy on supported plans (several instances across zones). Use deployment slots for safe swaps |
| Azure Functions | Zone redundancy on Premium and Flex Consumption plans |
| AKS | Node pools across zones, multiple system node pool nodes, and an uptime SLA tier. Use pod disruption budgets |
| Container Apps | Zone redundant environments |
| Service Bus Premium, Event Hubs | Zone redundant by default in supported regions, with geo disaster recovery pairing |
| Key Vault | Replicated within the region and paired region automatically |
For multi region designs, choose active active (traffic everywhere, data geo replicated, higher cost) or active passive (standby region, cheaper, longer failover). Use Front Door or Traffic Manager to steer users. Keep state out of the compute tier so instances are interchangeable.
Designing for failure
- Remove single points of failure, including DNS, identity and shared services.
- Use health probes and graceful degradation.
- Test with failover drills and Azure Chaos Studio.
- Aim each component's SLA so the composite SLA (the product of component SLAs) meets the target. Two components in series each at 99.9 give about 99.8.
- Use paired regions for staged platform updates and prioritised recovery, but they are not required.
Choosing quickly
| Requirement | Answer |
|---|---|
| 99.99 percent and survive a datacenter failure for a stateless VM app | Two or more instances across availability zones, such as a flexible scale set behind a Standard Load Balancer |
| Protect against rack failure only, same datacenter, low cost | An availability set |
| Zone failure must not break NVA routing | Internal Standard Load Balancer, zone redundant, HA ports |
| Regional outage with DNS failover for any protocol | Traffic Manager across two regions |
| Keep a web app running through a zone failure | App Service zone redundancy with several instances |
A worked scenario
A plant system runs a stateless API on one VM and must reach 99.99 percent and survive a datacenter loss with minimal change. The architect moves it to a flexible scale set across three zones, fronted by a zone redundant Standard Load Balancer with health probes, adds autoscale and automatic repairs, and keeps state in a zone redundant database. For a regional outage, a second region and Front Door are added later.
What to remember for the exam
- SLAs: single VM on premium disks 99.9, availability set 99.95, availability zones 99.99.
- A zonal VM alone does not survive a zone failure. Use instances in several zones.
- Flexible orchestration is recommended for new scale sets. The mode cannot be changed later.
- Standard Load Balancer with a zone redundant frontend is the HA choice. The Basic SKU is retired.
- Composite SLA is the product of component SLAs.
"Survive a datacenter failure" means zones. "Survive a region failure" means multi region.
How the exam asks about this
- "Give a VM based service a 99.99 percent SLA." Two or more VMs across availability zones.
- "Protect only against hardware faults in one datacenter." An availability set.
- "A single next hop for appliances that survives a zone failure." A Standard internal load balancer with a zone redundant frontend and HA ports.
- "Avoid DNS caching delays when failing over a web app." Azure Front Door.
Common mistakes
Using one zonal VM and calling it resilient.
Adding a load balancer but leaving instances in one zone.
Using the Basic Load Balancer. It is retired.
Ignoring the composite SLA.
Check yourself
Which option gives the 99.99 percent VM SLA?
Two or more VMs across availability zones.
Which scale set orchestration mode is recommended for new workloads?
Flexible.
How is a composite SLA calculated?
By multiplying the SLAs of the components in series.
Topic 3 of 4 in Design business continuity solutions
Test yourself on Design business continuity solutions
The full Microsoft AZ-305 question bank has 755 questions, with timed practice exams and an explanation for every answer.
This study guide is independent and is not affiliated with, endorsed by, or sponsored by Microsoft. Vendor names, certification names and exam codes are trademarks of their respective owners and are used for identification only.