Optimize Generative AI Systems and Model Performance · Topic 2 of 3
Hybrid Search and RAG Evaluation with A/B Testing
AI-300 optimization: combine keyword and vector search with semantic ranking in Azure AI Search, then evaluate RAG with relevance metrics and A/B tests.
- 5 min
- Includes a diagram
- Hybrid equals keyword (BM25) plus vector, merged with Reciprocal Rank Fusion.
- The semantic ranker reranks the top results and gives a score from 0 to 4.
- Measure retrieval with precision, recall, MRR, NDCG; measure answers with groundedness and relevance.
What it is
Hybrid search runs a keyword query and a vector query together and merges the results, so exact terms and meaning both count. A semantic ranker can then re-order the top results. To know whether a change really improves a RAG system, you measure it with relevance metrics offline and confirm with an A/B test online.
How it works
Why hybrid
| Search type | Strong at | Weak at |
|---|---|---|
| Keyword (BM25) | Exact words: product codes, error numbers, names | Synonyms and paraphrases |
| Vector | Meaning, paraphrase, other languages | Exact identifiers, rare terms |
| Hybrid | Both | Slightly more cost and complexity |
In Azure AI Search a single request can carry a text query and one or more vector queries. The separate result lists are fused with Reciprocal Rank Fusion (RRF), which rewards documents that rank well in either list and best of all in both. Because RRF uses ranks, not raw scores, keyword and vector scores do not need to be on the same scale.
from azure.search.documents import SearchClient
from azure.search.documents.models import VectorizedQuery

vector_query = VectorizedQuery(
    vector=query_embedding,
    k_nearest_neighbors=50,
    fields="contentVector",
)

results = search_client.search(
    search_text="reset vpn token",
    vector_queries=[vector_query],
    query_type="semantic",
    semantic_configuration_name="default",
    select=["title", "chunk"],
    top=5,
)
The search_text drives the keyword leg, vector_queries the vector leg, and query_type="semantic" with a semantic configuration adds reranking.
The semantic ranker
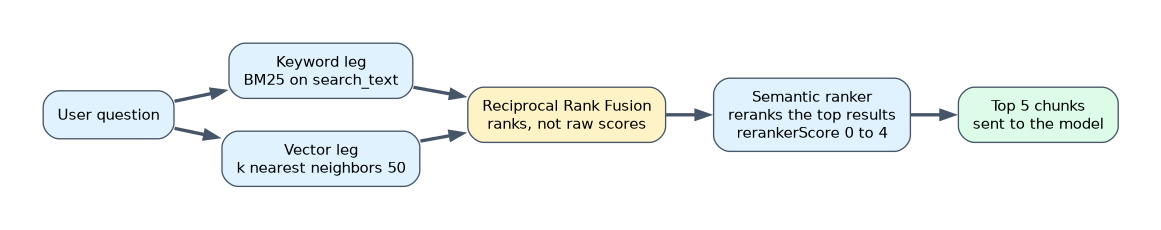 The semantic ranker applies a language model trained for relevance to the top results from the first stage and re-orders them. It adds a
@search.rerankerScore (0 to 4), and can return captions and answers. It improves ranking for natural language questions, particularly when wording differs from the document. You first retrieve broadly (for example the top 50), then rerank and pass only the best few to the model.
Optimizing hybrid search
- Choose
kfor the vector leg andtopfor the final result deliberately. - Weight the vector query if keyword matches should count less (or more).
- Restrict candidates with filters on metadata.
- Use scoring profiles to boost fields such as title.
- Pick a language analyzer suited to the content.
- Compare vector only, keyword only, hybrid and hybrid with reranking on the same labelled queries; the best mix depends on the data.
Relevance metrics for retrieval and RAG
| Metric | Meaning |
|---|---|
| Precision at k | Share of the top k results that are relevant |
| Recall at k | Share of all relevant documents found in the top k |
| MRR (mean reciprocal rank) | Average of 1 divided by the rank of the first relevant result |
| NDCG | Gain from relevant results, weighted higher when they rank higher |
| Retrieval evaluator | AI assisted score of how well the retrieved context fits the query |
| Groundedness, relevance, response completeness | Whether the generated answer uses the context and covers the question |
Evaluate retrieval and generation separately. Poor recall means search is the problem; good retrieval but low groundedness points to the prompt or model. The azure-ai-evaluation package offers evaluators for these (see the earlier chapter), and labelled queries with known relevant chunks let you compute precision, recall, MRR and NDCG yourself.
A/B testing
Offline metrics predict; an A/B test confirms with real users.
- Hypothesis: change a single thing (for example "hybrid with reranker beats vector only").
- Offline gate: the variant must beat the baseline on the evaluation set and pass safety checks.
- Split traffic: route a share of users to B using a feature flag service such as Azure App Configuration, keeping each user in the same group.
- Measure: online signals such as thumbs up or down, task completion or escalation rate, plus latency and token cost, from your telemetry.
- Decide: run long enough for a meaningful sample, check significance, watch guardrail metrics (safety, latency), then roll out or revert.
An alternative to full exposure is shadow testing, which runs B on copies of live requests without showing its answers.
A worked example
Searches for "ERR_4471" fail under vector only search. The team switches to hybrid, which fixes exact codes, and adds the semantic ranker, which lifts NDCG at 5 from 0.61 to 0.70 offline. An A/B test sends 10 percent of users to the new pipeline; thumbs up rises while p95 latency increases by 120 ms, which the product owner accepts.
How the exam asks about this
- "Users search by exact error codes and by natural language." Hybrid search.
- "Improve ordering of the top results without changing the index." Add the semantic ranker.
- "Prove a retrieval change helps real users." A/B test with a feature flag and success metrics.
What to remember for the exam
- Hybrid equals keyword (BM25) plus vector, merged with Reciprocal Rank Fusion.
- The semantic ranker reranks the top results and gives a score from 0 to 4.
- Measure retrieval with precision, recall, MRR, NDCG; measure answers with groundedness and relevance.
- Evaluate offline first, then A/B test with a controlled traffic split.
- Change one variable per experiment.
A better offline score does not guarantee better user outcomes. Confirm with online measurement and watch latency and cost.
Common mistakes
Trusting only the final answer quality. Without retrieval metrics you cannot find the cause.
Comparing on different datasets. Variants must use the same queries.
Ending the A/B test early. Small samples produce false winners.
Check yourself
How does hybrid search merge keyword and vector results?
With Reciprocal Rank Fusion, which combines ranks from both lists.
What does the semantic ranker add?
A language model based reranking of the top results, with a reranker score from 0 to 4.
Why run an A/B test after offline evaluation?
To confirm real user outcomes, latency and cost before full rollout.
Topic 2 of 3 in Optimize Generative AI Systems and Model Performance
Test yourself on Optimize Generative AI Systems and Model Performance
The full Microsoft AI-300 question bank has 650 questions, with timed practice exams and an explanation for every answer.
This study guide is independent and is not affiliated with, endorsed by, or sponsored by Microsoft. Vendor names, certification names and exam codes are trademarks of their respective owners and are used for identification only.