Implement Generative AI Quality Assurance and Observability · Topic 2 of 3
Safety Evaluations and Automated Evaluation Workflows
AI-300 QA: run risk and safety evaluators for harmful content, write custom evaluators and gate releases with thresholds in a GitHub Actions workflow.
- 5 min
- Includes a diagram
- Safety evaluators need a Foundry project; quality evaluators need a judge model.
- Four harm categories: violence, sexual, self harm, hate and unfairness.
- Indirect attack evaluator targets prompt injection through documents.
What it is
Risk and safety evaluators score whether an app produces or is manipulated into harmful output. They run on the Foundry safety evaluation service, so they need a Foundry project rather than your own judge model. Automated evaluation workflows run both quality and safety evaluators in CI/CD, add custom evaluators for your own rules, and fail the build when scores drop.
How it works
Risk and safety evaluators
| Evaluator | Detects |
|---|---|
| Violence | Violent content |
| Sexual | Sexual content |
| Self harm | Content about self harm |
| Hate and unfairness | Hateful or unfair content about groups |
| Content safety (composite) | Runs the four harm categories together |
| Protected material | Copyrighted text or code reproduced |
| Indirect attack | Hidden instructions inside documents or tool results trying to hijack the model |
| Code vulnerability | Insecure patterns in generated code |
| Ungrounded attributes | Inferring sensitive attributes about a person that the context does not support |
Harm evaluators return a severity label and a numeric score (a scale from 0 to 7, grouped as very low, low, medium and high), a reason, and a pass or fail result against a threshold. The default threshold is 3, so a score at or below it passes. Teams report a defect rate: the share of test rows at or above the unacceptable severity. In cloud evaluations the same evaluators are named builtin.violence, builtin.self_harm, builtin.hate_unfairness and so on.
from azure.ai.evaluation import evaluate, ContentSafetyEvaluator
from azure.identity import DefaultAzureCredential

safety = ContentSafetyEvaluator(
    credential=DefaultAzureCredential(),
    azure_ai_project="https://<resource>.services.ai.azure.com/api/projects/<project>",
)
result = evaluate(
    data="safety-data.jsonl",
    evaluators={"content_safety": safety},
    azure_ai_project="https://<resource>.services.ai.azure.com/api/projects/<project>",
)
Passing azure_ai_project to evaluate also logs the run to the Foundry project so it appears in the portal.
Adversarial testing supplies the data. The AdversarialSimulator in the evaluation package generates attack style conversations (jailbreak attempts, harmful content requests, indirect attacks) against your app, and the safety evaluators then score the responses. Foundry also offers an AI red teaming capability that automates probing with attack strategies. Run safety evaluations before release and on a schedule, because model and prompt changes alter behaviour.
Safety evaluation complements, and does not replace, guardrails / content filters on the deployment. Filters block at run time; evaluations measure how well the whole app holds up.
Custom evaluators
Any Python function that accepts named inputs and returns a dictionary of metrics can be an evaluator.
def answer_length(*, response: str, **kwargs):
    words = len(response.split())
    return {"answer_words": words, "within_limit": words <= 120}

class CitationCheck:
    def __call__(self, *, response: str, context: str, **kwargs):
        cited = "[source]" in response
        return {"has_citation": cited}

result = evaluate(
    data="eval-data.jsonl",
    evaluators={"length": answer_length, "citation": CitationCheck()},
)
Use code based custom evaluators for rules you can compute (format, length, forbidden words, citation present). Use prompt based custom evaluators, which wrap your own rubric in a judge prompt, for subjective qualities such as brand tone. Custom evaluators can be combined with built in ones in the same evaluate call.
Automate the workflow
name: genai-evaluation
on:
  pull_request:
    paths: ['prompts/**', 'src/**']
  schedule:
    - cron: '0 3 * * 1'
permissions:
  id-token: write
  contents: read
jobs:
  evaluate:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - uses: azure/login@v2
        with:
          client-id: ${{ vars.AZURE_CLIENT_ID }}
          tenant-id: ${{ vars.AZURE_TENANT_ID }}
          subscription-id: ${{ vars.AZURE_SUBSCRIPTION_ID }}
      - run: pip install azure-ai-evaluation azure-identity
      - run: python eval/run_eval.py --min-groundedness 4.0 --max-defect-rate 0.0
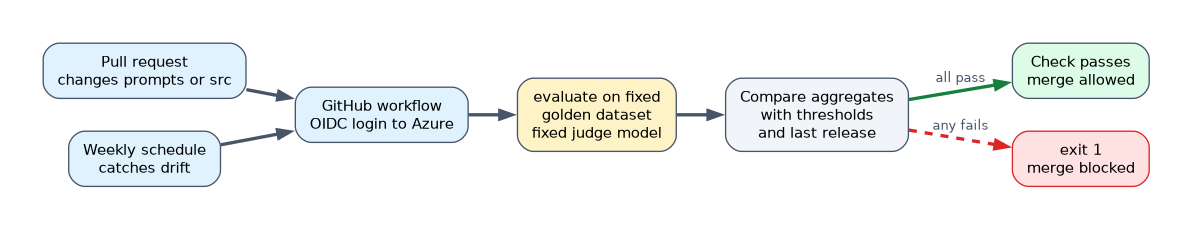
The script calls evaluate, compares each aggregate with its threshold, and calls sys.exit(1) if any check fails. Good practice: a fixed golden dataset, a fixed judge model, thresholds agreed in advance, results stored as artifacts, and comparison with the previous release as a baseline so regressions stand out. A scheduled run catches drift when no code changed.
A worked example
A pull request edits a prompt. The workflow runs groundedness, relevance, the composite content safety evaluator on an adversarial set, and the custom citation check. Groundedness holds at 4.4, but two adversarial rows score medium severity for hate and unfairness, so the check fails and the merge is blocked until the prompt is fixed.
How the exam asks about this
- "Test whether users can trick the app into harmful content." AdversarialSimulator data scored by safety evaluators.
- "Enforce a company specific formatting rule in evaluation." A custom code based evaluator.
- "Stop deployment when quality drops." A workflow step that compares metrics to thresholds and exits non zero.
What to remember for the exam
- Safety evaluators need a Foundry project; quality evaluators need a judge model.
- Four harm categories: violence, sexual, self harm, hate and unfairness.
- Indirect attack evaluator targets prompt injection through documents.
- Custom evaluators are plain callables returning a dictionary.
- Automate with thresholds, fixed datasets and non zero exit codes.
Content filters and safety evaluations are different. One blocks at run time; the other measures behaviour in testing.
Common mistakes
Running safety checks once. Behaviour changes with prompts and models, so rerun.
No baseline. A score of 4.0 means little without the previous result.
Only normal inputs. Without adversarial data you never see the failures.
Check yourself
Which evaluator finds hidden instructions in retrieved documents?
The indirect attack evaluator.
What does a custom evaluator return?
A dictionary of metric names and values.
How does a workflow block a bad release?
It compares metrics with thresholds and exits with a non zero code so the required check fails.
Topic 2 of 3 in Implement Generative AI Quality Assurance and Observability
Test yourself on Implement Generative AI Quality Assurance and Observability
The full Microsoft AI-300 question bank has 650 questions, with timed practice exams and an explanation for every answer.
This study guide is independent and is not affiliated with, endorsed by, or sponsored by Microsoft. Vendor names, certification names and exam codes are trademarks of their respective owners and are used for identification only.