Cloud Platform and Infrastructure Security · Topic 5 of 5
Cloud Business Continuity and Disaster Recovery
CCSP cloud BC and DR: strategies from backup to active-active, RTO, RPO and recovery service level, and creating, implementing and testing the plan.
- 5 min
- Includes a diagram
- RTO is time to restore; RPO is acceptable data loss; RTO must be less than MTD.
- Recovery service level is the reduced capacity acceptable during recovery.
- Backup and restore, pilot light, warm standby, active-active: rising cost, falling RTO and RPO.
What it is
Business continuity (BC) keeps critical business functions running during a disruption. Disaster recovery (DR) restores the IT systems those functions need. In the cloud, DR can use another zone, another region, another provider or the cloud as a recovery site for on-premises systems.
The plan starts from business requirements, chooses a strategy that meets them at acceptable cost, and is proven by testing.
How it works
Business requirements
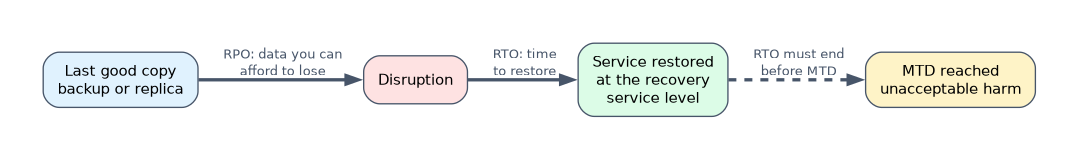
| Term | Meaning |
|---|---|
| RTO (recovery time objective) | Maximum time to restore a service after disruption |
| RPO (recovery point objective) | Maximum acceptable data loss, measured in time back from the disruption |
| Recovery service level | The capacity or performance the service must provide while in recovery mode, for example 50% of normal |
| MTD or MAO | Maximum tolerable downtime, the point where the business suffers unacceptable harm; RTO must be shorter |
An RPO of 15 minutes means backups or replication must capture data at least every 15 minutes. An RTO of one hour means the whole failover, including people and decisions, must finish inside an hour.
BC and DR strategies
| Strategy | How it works | RTO and RPO | Cost |
|---|---|---|---|
| Backup and restore | Data backed up to another region or provider; infrastructure rebuilt on demand | Hours to days | Lowest |
| Pilot light | Core components such as databases replicate continuously; the rest is built at failover | Tens of minutes to hours | Low |
| Warm standby | A scaled down full environment runs continuously and scales up at failover | Minutes | Medium |
| Active-active (multi-site) | Full capacity in two or more locations serving traffic | Near zero | Highest |
Scenarios to plan for include: on-premises primary with cloud as DR site; cloud primary with DR in another region of the same provider; and cloud primary with DR at a different provider, which protects against provider wide failure but adds portability work.
Cloud specific considerations
- Availability zones protect against a data center failure; regions protect against a regional disaster.
- Infrastructure as code lets the environment be rebuilt quickly and consistently.
- Capacity at failover may not be guaranteed in a shared region during a large event; reserved capacity reduces this risk.
- Backups need separation: different account, credentials and ideally immutability, so ransomware or an account compromise cannot delete them.
- Dependencies: DNS, identity provider, key management and third-party SaaS must also be available in the DR scenario.
- Data location: the DR region must be legally permitted for the data.
Creating the plan
A BC/DR plan documents scope, roles and contacts, activation criteria and who declares a disaster, communication steps, step by step recovery procedures for each system in priority order, and the return to normal operations, called failback.
Implementing the plan
Put the technical pieces in place: replication, backups, DR accounts, templates, runbooks, monitoring of replication lag, and training for the people who will run it.
Testing the plan
| Test | What happens | Disruption |
|---|---|---|
| Checklist (read-through) | Owners review the plan for accuracy | None |
| Walkthrough or tabletop | Team talks through a scenario step by step | None |
| Simulation | Scenario practised with simulated systems and decisions | Low |
| Parallel | Recovery systems are brought up and run alongside production | Low |
| Full interruption | Production is shut down and recovery systems take over | High |
The cloud makes realistic tests cheaper, because a full recovery environment can be built, tested and removed. Tests should measure actual recovery time and data loss against RTO and RPO, and every test should update the plan.
A worked example
An online travel agency sets RTO at 30 minutes and RPO at 5 minutes for bookings, and RTO 24 hours with RPO 24 hours for internal reporting. Bookings get a warm standby in a second region with continuous database replication. Reporting uses nightly backup and restore.
A parallel test shows bookings recovered in 42 minutes because DNS changes were manual. The team automates the DNS failover, retests at 18 minutes and records the result in the plan.
How the exam asks about this
- "Which metric defines how much data loss is acceptable?" RPO.
- "Which DR strategy has the LOWEST cost and longest recovery time?" Backup and restore.
- "Which test brings recovery systems up without interrupting production?" A parallel test.
What to remember for the exam
- RTO is time to restore; RPO is acceptable data loss; RTO must be less than MTD.
- Recovery service level is the reduced capacity acceptable during recovery.
- Backup and restore, pilot light, warm standby, active-active: rising cost, falling RTO and RPO.
- Zones protect against site failure; regions protect against regional disaster; another provider protects against provider failure.
- Test types run from checklist to full interruption; measure results against targets.
A full interruption test can cause the outage it is meant to prepare for. Run it only with senior management approval and after lower level tests have passed.
Common mistakes
Mixing up RTO and RPO. RTO is about time to recover the service; RPO is about how much data you can lose.
Forgetting dependencies. A recovered application is useless if the identity provider or key service is not reachable in the DR region.
Backing up into the same account. Ransomware or a compromised administrator can delete both production and backups.
Check yourself
What does recovery service level describe?
The minimum capacity or performance the service must provide while it is running from recovery systems.
What is the difference between pilot light and warm standby?
Pilot light keeps only core components such as databases running and builds the rest at failover, while warm standby runs a scaled down full environment ready to scale up.
Why should DR tests measure actual recovery time?
To prove the strategy meets the RTO and RPO in practice and to find gaps, such as manual steps, that the plan missed.
Topic 5 of 5 in Cloud Platform and Infrastructure Security
Test yourself on Cloud Platform and Infrastructure Security
The full ISC2 CCSP question bank has 900 questions, with timed practice exams and an explanation for every answer.
This study guide is independent and is not affiliated with, endorsed by, or sponsored by ISC2. Vendor names, certification names and exam codes are trademarks of their respective owners and are used for identification only.