Storing the data · Topic 3 of 4
Managing a Data Lake with Cloud Storage and BigLake
Run a data lake on Cloud Storage: zones, discovery, BigLake access control, cost controls, processing with Dataproc, Dataflow and BigQuery, monitoring.
- 5 min
- Includes a diagram
- Organize the lake into raw, curated and consumption zones.
- Dataplex discovery publishes Cloud Storage data as queryable tables in the catalog.
- BigLake delegates file access to a connection, enabling row and column security.
What it is
A data lake keeps large volumes of raw and refined data as files in Cloud Storage, usually in open formats, so many engines can use it. Managing it means making the data discoverable, controlling who can read what, keeping costs in check, processing it efficiently and monitoring its health.
How it works
Organizing the lake
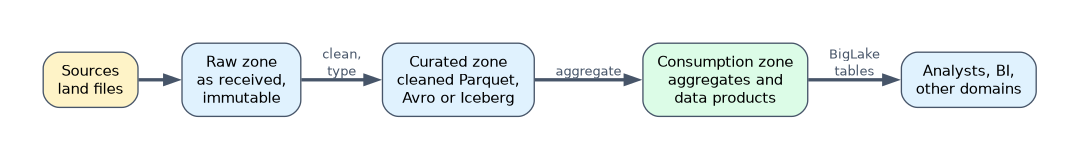
| Zone | Contents | Typical rules |
|---|---|---|
| Raw (landing) | Files exactly as received | Immutable, restricted access, colder storage after a period |
| Curated (refined) | Cleaned, typed, deduplicated data in Parquet, Avro or Iceberg | Partitioned by date folders, broad read access through tables |
| Consumption | Aggregates and data products | Shared with analysts and other domains |
Dataplex can organize buckets and datasets into lakes and zones so that metadata, discovery and data quality work across them.
Configuring data discovery
Dataplex discovery scans Cloud Storage data, infers schemas and partitions, and publishes tables that can be queried from BigQuery. The tables appear in the catalog with their technical metadata, where teams add owners, descriptions and glossary terms.
Configuring access
| Approach | Effect |
|---|---|
| IAM on buckets (uniform bucket-level access) | All-or-nothing access to files; users can bypass table rules by reading files directly |
| BigLake tables with a connection | Users get table permissions only; the connection's service account reads the files |
| Row access policies and policy tags on BigLake tables | Row and column security over files, enforced for BigQuery and for Spark through the BigQuery Storage Read API |
With BigLake, analysts need no access to the bucket. That access delegation is what makes fine-grained security over a lake possible.
CREATE EXTERNAL TABLE `prod-lake.curated.events`
WITH CONNECTION `prod-lake.eu.lake-conn`
WITH PARTITION COLUMNS
OPTIONS (
  format = 'PARQUET',
  uris = ['gs://lake-curated/events/*'],
  hive_partition_uri_prefix = 'gs://lake-curated/events',
  require_hive_partition_filter = TRUE,
  max_staleness = INTERVAL 4 HOUR,
  metadata_cache_mode = 'AUTOMATIC'
);
Metadata caching keeps file listings and statistics so queries do not list millions of objects each time. max_staleness sets how old that cache may be.
Cost controls
| Lever | Saves |
|---|---|
| Lifecycle rules or Autoclass on raw data | Storage cost for data that is rarely read |
| Columnar formats (Parquet) and date-partitioned folders | Bytes scanned per query |
| Compacting many small files into fewer large ones | Listing overhead and slow reads |
require_hive_partition_filter | Accidental full scans |
| BigQuery custom quotas and maximum bytes billed | Runaway query costs |
| Labels and budget alerts | Visibility of spend per team |
Processing data in the lake
| Engine | Fits |
|---|---|
| BigQuery over BigLake or Iceberg tables | SQL analytics without loading |
| Dataproc or Dataproc Serverless for Spark | Spark jobs, notebooks, large transformations |
| Dataflow | Batch and streaming pipelines writing curated files or tables |
A common job converts raw CSV or JSON into partitioned Parquet in the curated zone. That single step usually cuts query cost and time more than any other change.
When stems say "users query the raw CSV files and costs are high", the fix is to convert to a columnar, partitioned format and query through BigLake, not to buy more capacity.
Monitoring the data lake
- Cloud Monitoring metrics for bucket size, object count and request rates.
- Cloud Audit Logs for who read or changed data.
- Dataplex data quality and data profile scans on lake tables, with alerts on failures.
- Budget alerts and billing export to BigQuery for cost trends.
A worked example
A research company stores 2 PB of instrument output as CSV files. Analysts read the files directly with broad bucket permissions, queries are slow and costly, and one team must see only its own instruments.
The engineer converts the files to date-partitioned Parquet with a Dataproc Serverless batch job. BigLake tables with metadata caching replace direct file access, and bucket access is removed from analysts. A row access policy limits each team to its instruments, and raw CSV moves to Coldline after 90 days.
How the exam asks about this
- "Apply column-level security to Parquet files in Cloud Storage queried from BigQuery and Spark." BigLake tables with policy tags.
- "Analysts must not read lake files directly but must query them." Remove bucket access and grant access to BigLake tables that use a connection.
- "Queries over a lake with millions of small files are slow to start." Compact files and enable metadata caching on BigLake tables.
What to remember for the exam
- Organize the lake into raw, curated and consumption zones.
- Dataplex discovery publishes Cloud Storage data as queryable tables in the catalog.
- BigLake delegates file access to a connection, enabling row and column security.
- Columnar, partitioned files and lifecycle rules are the main cost levers.
- Monitor with Cloud Monitoring, audit logs and Dataplex data quality scans.
Granting analysts read access on the bucket defeats BigLake row and column security, because they can read the files directly.
Common mistakes
Querying raw CSV for everyday analytics. Convert once to partitioned Parquet; every later query is cheaper.
Leaving millions of tiny files. Small files slow listing and reading; compact them.
Treating the lake as ungoverned storage. Without discovery, catalog entries and quality checks, the lake becomes a swamp nobody trusts.
Check yourself
Why do BigLake tables allow fine-grained security over files?
Users are granted access to the table, while a connection's service account reads the files, so users never need bucket permissions.
What does BigLake metadata caching improve?
Query performance, by reusing cached file listings and statistics instead of listing objects on every query, within the max_staleness setting.
What is usually the biggest single cost fix for a CSV data lake?
Converting the files to a columnar, partitioned format such as Parquet so queries scan far fewer bytes.
Topic 3 of 4 in Storing the data
Test yourself on Storing the data
The full Google Cloud Professional Data Engineer question bank has 733 questions, with timed practice exams and an explanation for every answer.
This study guide is independent and is not affiliated with, endorsed by, or sponsored by Google Cloud. Vendor names, certification names and exam codes are trademarks of their respective owners and are used for identification only.