Data Preparation · Topic 2 of 2
Chunking, Retrieval Evaluation and Re-ranking
Databricks GenAI Engineer: chunking for document structure and model limits, parent child and semantic chunking, retrieval metrics and re-ranking.
- 5 min
- Includes a diagram
- Match chunking to structure: headings for manuals, recursive splitting for prose, whole units for tables.
- Chunks must fit the embedding model's input limit or the excess is lost.
- Overlap keeps ideas whole across boundaries; too much creates duplicates.
What it is
Chunking splits documents into pieces small enough to embed and retrieve, but large enough to carry a complete idea. The right strategy depends on the document structure and on two limits: the embedding model's maximum input and the context window of the LLM that reads the results.
After chunking, you evaluate retrieval to see whether the right chunks come back, and you can add a re-ranker that reorders the first results so the best ones reach the prompt.
How it works
Choosing a chunking strategy
| Strategy | How it splits | Fits |
|---|---|---|
| Fixed size with overlap | Every N tokens, repeating some tokens between chunks | Plain text with little structure |
| Recursive character | Tries paragraphs, then sentences, then words until the size fits | General prose; a safe default |
| Structure based | By Markdown or HTML headings, sections or pages | Manuals, policies, wiki pages |
| Sentence or paragraph | At natural sentence or paragraph boundaries | FAQs, short articles |
| Semantic | Where the meaning shifts, using embedding similarity between sentences | Long text that changes topic without headings |
Model constraints set the upper bound. A chunk longer than the embedding model's input limit is truncated, and the cut part is never represented. For example, databricks-bge-large-en accepts 512 tokens while databricks-gte-large-en accepts 8192.
The LLM context window limits how many chunks fit in the prompt. Chunks that are too small lose context; chunks that are too large mix topics, so their embedding is vague.
Overlap repeats the end of one chunk at the start of the next, so an idea split at a boundary still appears whole in one chunk. Too much overlap creates near duplicates that crowd the results.
Advanced chunking designs
- Parent and child (small to big): embed small child chunks, return the larger parent section to the LLM.
- Contextual headers: add the document title and section heading to each chunk's text before embedding.
- Metadata filters: store fields such as product, region or date, and filter on them at query time.
- Hybrid search: combine vector similarity with keyword matching, which helps with exact terms such as error codes.
Keep each table or code block whole in one chunk where it fits; rows split from their header lose their meaning.
Evaluating retrieval
Build an evaluation set of questions with the chunks or facts that should be retrieved, then measure.
| Metric | What it tells you |
|---|---|
| Precision at k | Share of the top k results that are relevant |
| Recall at k | Share of all relevant chunks found in the top k |
| NDCG | Whether relevant results are ranked near the top |
In MLflow 3, mlflow.genai.evaluate runs scorers over traced runs. The RAG judges are RetrievalRelevance (are the retrieved chunks relevant to the query), RetrievalGroundedness (is the answer supported by the retrieved chunks) and RetrievalSufficiency (do the chunks contain everything needed). RetrievalSufficiency needs ground truth such as expected facts; the other two do not.
import mlflow
from mlflow.genai.scorers import RetrievalRelevance, RetrievalSufficiency
mlflow.genai.evaluate(
    data=eval_df,
    predict_fn=my_rag_app,
    scorers=[RetrievalRelevance(), RetrievalSufficiency()],
)
These judges read the retrieved chunks from the trace, so the retriever step must be traced.
Re-ranking
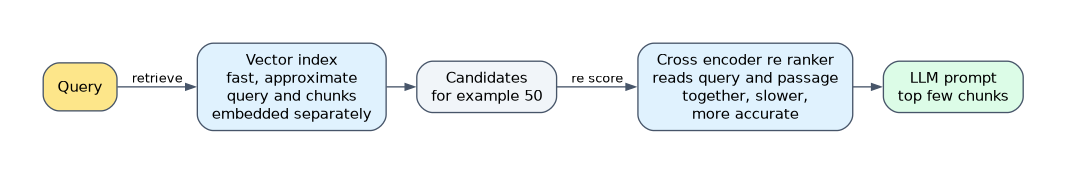 A vector index compares the query embedding with each chunk embedding separately, which is fast but approximate. A cross-encoder re-ranker reads the query and a passage together and gives a more accurate relevance score.
Because that is slower, it runs only on a small candidate set: retrieve, say, 50 chunks, re-rank them, and pass the top few to the LLM.
Mosaic AI Vector Search (called AI Search in newer docs) can apply a re-ranker within a similarity_search call through its reranker parameter, a DatabricksReranker that names the columns to score. num_results still sets how many results come back.
results = index.similarity_search(
    query_text="How do I reset a locked account?",
    columns=["chunk_id", "chunk_text", "doc_path"],
    num_results=5,
    reranker=DatabricksReranker(columns_to_rerank=["chunk_text"]),
)
How the exam asks about this
- "Answers miss details split across chunk boundaries." Add overlap or chunk by section so related text stays together.
- "Short chunks match well but the LLM lacks context to answer." Use parent and child chunking: retrieve the small chunk, return its parent.
- "The right chunk is retrieved but ranked eighth, and only the top three reach the prompt." Add a re-ranker over a larger candidate set.
What to remember for the exam
- Match chunking to structure: headings for manuals, recursive splitting for prose, whole units for tables.
- Chunks must fit the embedding model's input limit or the excess is lost.
- Overlap keeps ideas whole across boundaries; too much creates duplicates.
- Parent and child chunking gives precise matching with full context.
- Recall at k shows whether the right chunks are found; precision at k shows how much noise comes with them.
- A re-ranker reorders a small candidate set after retrieval; it does not search the whole index.
Do not raise num_results to fix poor ranking. More chunks add noise and cost; retrieve a larger candidate set for a re-ranker and still pass only the top few.
Common mistakes
One chunk size for every document. A FAQ, a manual and a spreadsheet export need different splitting. Pick the strategy per document type.
Judging retrieval only by final answers. A good answer can hide weak retrieval. Measure retrieval with its own metrics and judges.
Treating re-ranking as a replacement for search. A cross-encoder is too slow to score every chunk. It refines the results the index already returned.
Check yourself
Why must chunks fit the embedding model's input limit?
Text beyond the limit is truncated before embedding, so that part is never represented and cannot be retrieved.
Which retrieval judge needs ground truth?
RetrievalSufficiency, because it checks the retrieved chunks against expected facts; RetrievalRelevance and RetrievalGroundedness do not need them.
Why is a re-ranker applied after retrieval instead of to the whole index?
It scores the query and each passage together, which is accurate but slow, so it runs only on a small candidate set.
Topic 2 of 2 in Data Preparation
Test yourself on Data Preparation
The full Databricks Generative AI Engineer Associate question bank has 600 questions, with timed practice exams and an explanation for every answer.
This study guide is independent and is not affiliated with, endorsed by, or sponsored by Databricks. Vendor names, certification names and exam codes are trademarks of their respective owners and are used for identification only.