Assembling and Deploying Applications · Topic 1 of 4
Chains, PyFunc Models and Unity Catalog Registration
Databricks GenAI Engineer: code a chain, wrap it in a pyfunc model with pre and post processing, pick RAG model elements and register to Unity Catalog.
- 5 min
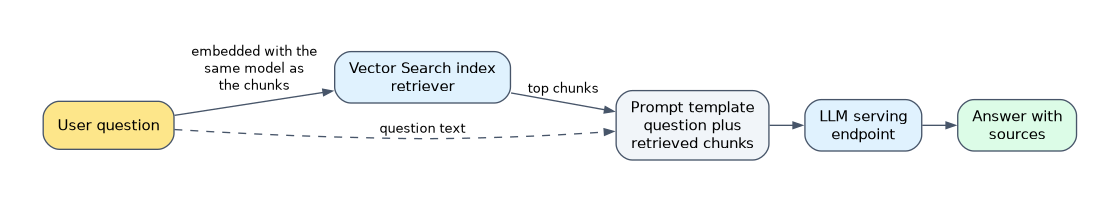
- Includes a diagram
mlflow.set_registry_uri("databricks-uc")plus acatalog.schema.modelname registers to Unity Catalog.- Unity Catalog models need a signature; an input example lets MLflow infer it.
- Heavy setup goes in
load_context; per request logic goes inpredict.
What it is
A chain links a prompt, a retriever and an LLM so one call turns a question into an answer. To deploy it, you package the chain as an MLflow model, log it with everything it needs, and register it in Unity Catalog so it can be versioned, governed and served.
The pyfunc flavor is the general wrapper: a Python class whose predict method can clean the input before the chain runs and reshape the output after it.
How it works
A simple chain
A minimal chain in LangChain style is a prompt template piped into a chat model and an output parser. ChatDatabricks from the databricks_langchain package calls a Databricks serving endpoint.
from databricks_langchain import ChatDatabricks
from langchain_core.prompts import ChatPromptTemplate
from langchain_core.output_parsers import StrOutputParser

prompt = ChatPromptTemplate.from_template("Use this context: {context}\nQuestion: {question}")
llm = ChatDatabricks(endpoint="databricks-meta-llama-3-3-70b-instruct")
chain = prompt | llm | StrOutputParser()
Read requirements literally. If the scenario asks for a plain string answer, the chain ends in a string output parser; if it must ground answers in documents, a retriever fills {context} before the prompt.
Wrapping the chain in pyfunc
Subclass mlflow.pyfunc.PythonModel. load_context runs once when the model loads, so build clients and the chain there; predict(self, context, model_input, params=None) runs per request.
class RagChain(mlflow.pyfunc.PythonModel):
    def load_context(self, context):
        self.chain = build_chain()                   # retriever + prompt + LLM
    def predict(self, context, model_input, params=None):
        question = model_input["question"][0].strip()  # pre processing
        answer = self.chain.invoke({"question": question})
        return [answer.strip()]                      # post processing
Pre processing is where you validate, mask or rewrite input; post processing is where you strip text, add citations or enforce a format. Neither belongs in the prompt when plain code can do it reliably.
The elements a RAG model needs
| Element | What it is | Why it matters |
|---|---|---|
| Model flavor | pyfunc, or an agent interface such as ResponsesAgent | Decides how MLflow loads and serves it |
| Embedding model | The same endpoint used to embed the chunks | Query and chunk vectors must share one space |
| Retriever | A Vector Search index lookup | Supplies the context passages |
| Dependencies | Pinned packages captured at logging | The serving container installs them |
| Input example | A sample request | Used to infer the signature and test the model |
| Model signature | The input and output schema | Required for Unity Catalog registration |
| Resources | Endpoints and indexes the model calls | Enables automatic authentication when served |
Databricks recommends models from code for agents: the class lives in a Python file that calls mlflow.models.set_model(...), and you pass the file path as python_model. For agents, ResponsesAgent is the current interface; MLflow infers its signature automatically, while a plain pyfunc needs a signature or an input example.
Logging and registering to Unity Catalog
Point the registry at Unity Catalog, then log with a three level name. In MLflow 3, name replaces the deprecated artifact_path.
mlflow.set_registry_uri("databricks-uc")
with mlflow.start_run():
    info = mlflow.pyfunc.log_model(
        name="rag_chain", python_model=RagChain(),
        input_example={"question": ["What is Delta Lake?"]},
        resources=[DatabricksVectorSearchIndex(index_name="main.docs.chunks_index")],
        registered_model_name="main.docs.rag_chain")
You can also log first and call mlflow.register_model(info.model_uri, "main.docs.rag_chain"). Each registration creates a new model version; aliases such as champion point serving and jobs at the version you approve.
How the exam asks about this
- "Registration to Unity Catalog fails with a missing signature error." Add an input example or an explicit signature when logging.
- "User input must have extra whitespace removed and answers trimmed to the first paragraph." Use a pyfunc model with pre and post processing in
predict. - "The model is served but cannot reach the Vector Search index." Declare the index in resources when logging so automatic authentication covers it.
What to remember for the exam
mlflow.set_registry_uri("databricks-uc")plus acatalog.schema.modelname registers to Unity Catalog.- Unity Catalog models need a signature; an input example lets MLflow infer it.
- Heavy setup goes in
load_context; per request logic goes inpredict. - Embed queries with the same model that embedded the chunks.
- Declare every Databricks endpoint, index or function the model calls in
resources. - Pin dependencies at logging time so the serving container matches development.
Do not change the embedding model in the chain without re embedding the index. Mismatched embedding models return irrelevant chunks with no error at all.
Common mistakes
Putting formatting rules only in the prompt. If an answer must always be trimmed or always carry a field, code it in post processing. The LLM can ignore a prompt instruction; code cannot.
Building clients inside predict. Creating the retriever or LLM client on every request adds latency. Build them once in load_context.
Registering with a two level name. Unity Catalog needs catalog, schema and model. The workspace model registry uses a bare name and is not the recommended target.
Check yourself
Why does a pyfunc model need an input example or signature before registering to Unity Catalog?
Unity Catalog requires every model version to have a signature, and MLflow infers it from the input example when no explicit signature is given.
Where should a chain trim and format its final answer?
In the post processing step of the pyfunc predict method, after the chain returns, because code enforces the format reliably.
What does the resources argument of log_model do?
It records the endpoints, indexes and functions the model calls, so the serving endpoint gets automatic credentials for them.
Topic 1 of 4 in Assembling and Deploying Applications
Test yourself on Assembling and Deploying Applications
The full Databricks Generative AI Engineer Associate question bank has 600 questions, with timed practice exams and an explanation for every answer.
This study guide is independent and is not affiliated with, endorsed by, or sponsored by Databricks. Vendor names, certification names and exam codes are trademarks of their respective owners and are used for identification only.