Data Transformation and Modeling · Topic 3 of 3
Gold Layer Objects and Data Quality
Databricks DEA Gold layer: views vs materialized views vs streaming tables vs tables in Unity Catalog, expectations, CHECK constraints and quarantine.
- 6 min
- Includes a diagram
- A view stores nothing and runs on every query; a materialized view stores a precomputed result.
- Materialized views refresh on a schedule, on upstream updates or with REFRESH; a failed refresh keeps the last good data.
- Streaming tables process each new row once and fit append only sources.
What it is
The Gold layer holds the business ready objects that BI and analytics teams query: aggregates, dimensions and reporting tables in Unity Catalog. Databricks offers four object types for it, and they differ in when the result is computed and whether it is stored.
Data quality checks make sure silver and gold data can be trusted. In Lakeflow Declarative Pipelines they are expectations; on any Delta table they are constraints.
How it works
The four Gold object types
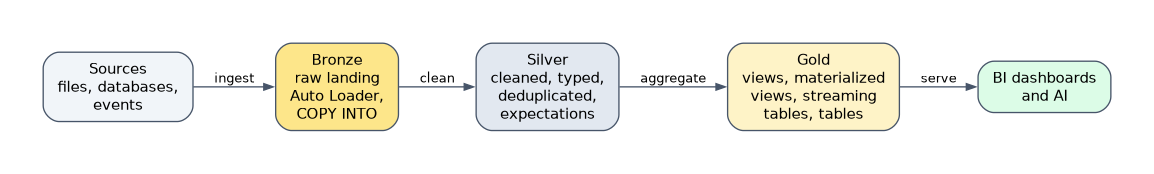
| Object | Stores data | Computed | Fits when |
|---|---|---|---|
| View | No | Every time it is queried | Results must always be current, with no stored copy |
| Materialized view | Yes | At refresh; Databricks can refresh incrementally | Dashboards need fast, precomputed aggregates and some delay is acceptable |
| Streaming table | Yes | Incrementally; each new source row processed once | Append only sources such as events or files, with low latency |
| Table (Delta) | Yes | When your job writes it | You control every write yourself, such as MERGE logic in a job |
A view costs nothing to store but repeats its work on every query. A materialized view moves that work to refresh time, so many dashboard users read a stored result.
Building them
A view and a table are standard SQL:
CREATE OR REPLACE VIEW main.gold.active_customers AS
SELECT customer_id, region FROM main.silver.customers WHERE active;
CREATE OR REPLACE TABLE main.gold.daily_sales AS
SELECT order_date, sum(amount) AS revenue FROM main.silver.orders GROUP BY order_date;
A materialized view can be created in Databricks SQL on a pro or serverless SQL warehouse, or inside a pipeline. Its create and refresh run on serverless pipelines. The SCHEDULE clause refreshes it on a timer; TRIGGER ON UPDATE refreshes it when upstream data changes.
CREATE MATERIALIZED VIEW main.gold.sales_by_region
SCHEDULE EVERY 1 HOUR
AS SELECT region, sum(amount) AS revenue
FROM main.silver.orders GROUP BY region;
REFRESH MATERIALIZED VIEW main.gold.sales_by_region;
A streaming table reads its source with STREAM, so only new rows are processed on each update:
CREATE OR REFRESH STREAMING TABLE main.silver.events
AS SELECT * FROM STREAM read_files('/Volumes/main/raw/events', format => 'json');
If a materialized view refresh fails, the view keeps serving the last successfully refreshed data.
Expectations in pipelines
An expectation is a named condition on a streaming table or materialized view in a pipeline. The action decides what happens to rows that fail it.
| Clause | Bad rows | Pipeline update |
|---|---|---|
EXPECT (cond) | Kept in the target; violations counted | Continues |
EXPECT (cond) ON VIOLATION DROP ROW | Dropped; violations counted | Continues |
EXPECT (cond) ON VIOLATION FAIL UPDATE | None written | Stops with an error |
CREATE OR REFRESH STREAMING TABLE silver_orders (
  CONSTRAINT valid_id EXPECT (order_id IS NOT NULL) ON VIOLATION DROP ROW,
  CONSTRAINT valid_amount EXPECT (amount >= 0)
) AS SELECT * FROM STREAM(bronze_orders);
In Python the same actions are the decorators @dp.expect, @dp.expect_or_drop and @dp.expect_or_fail, with expect_all variants that take a dictionary of rules. Metrics for warn and drop appear on the dataset's Data quality tab in the pipeline UI and in the pipeline event log.
Constraints on Delta tables
Outside pipelines, Delta tables enforce NOT NULL and CHECK constraints. A write containing any violating row fails as a whole, and nothing from it is committed.
ALTER TABLE main.silver.orders ALTER COLUMN order_id SET NOT NULL;
ALTER TABLE main.silver.orders ADD CONSTRAINT valid_amount CHECK (amount >= 0);
Adding a constraint fails if existing rows already violate it, so clean the data first.
Quarantining bad rows
When bad rows must be kept for review rather than dropped, split the data on the rule. Valid rows go to the silver table and the inverse filter sends invalid rows to a quarantine table. Simple validation queries, such as null counts, duplicate key counts and row counts against the source, confirm a load before Gold objects refresh.
How the exam asks about this
- "Executives' dashboard runs the same heavy aggregation hundreds of times a day; hourly freshness is fine." Use a materialized view with a schedule.
- "Bad rows must be removed from the silver table but the pipeline must keep running and report how many were removed." Use EXPECT ... ON VIOLATION DROP ROW.
- "Give analysts a filtered subset of a table that is always current, without storing a copy." Use a view.
What to remember for the exam
- A view stores nothing and runs on every query; a materialized view stores a precomputed result.
- Materialized views refresh on a schedule, on upstream updates or with REFRESH; a failed refresh keeps the last good data.
- Streaming tables process each new row once and fit append only sources.
EXPECTalone keeps bad rows and records metrics; DROP ROW drops them; FAIL UPDATE stops the update.- Delta
CHECKandNOT NULLconstraints reject the whole write when one row violates them. - Materialized views in Databricks SQL need a pro or serverless SQL warehouse.
An expectation with no ON VIOLATION clause does not remove anything. If the requirement says bad rows must not reach the table, the answer needs DROP ROW or FAIL UPDATE.
Common mistakes
Choosing a view for a heavy dashboard. A view recomputes the query for every user. When the same aggregate is read often and slight staleness is fine, a materialized view is cheaper and faster.
Using a streaming table for data that changes. A streaming table expects new rows appended to its source. Aggregates over updated or deleted source rows belong in a materialized view.
Expecting a CHECK constraint to drop rows. A constraint fails the write; it never filters. To keep loading while removing bad rows, use an expectation with DROP ROW or a quarantine split.
Check yourself
What does a materialized view return if its latest refresh fails?
It keeps serving the data from the last successful refresh. The failed refresh does not empty or corrupt it.
Which expectation clause stops the pipeline update when a row violates the rule?
ON VIOLATION FAIL UPDATE.EXPECTalone keeps the row and records a metric, andDROP ROWremoves it.What happens when an INSERT contains one row that breaks a CHECK constraint on a Delta table?
The whole write fails and none of its rows are committed. CHECK constraints reject, they do not filter.
Topic 3 of 3 in Data Transformation and Modeling
Test yourself on Data Transformation and Modeling
The full Databricks Data Engineer Associate question bank has 598 questions, with timed practice exams and an explanation for every answer.
This study guide is independent and is not affiliated with, endorsed by, or sponsored by Databricks. Vendor names, certification names and exam codes are trademarks of their respective owners and are used for identification only.