Operational Efficiency and Optimization for GenAI Applications · Topic 3 of 7
Throughput, Capacity Planning and Auto Scaling
Keep FM workloads inside quotas with batch inference, service tiers, Provisioned Throughput, cross-Region inference and SageMaker AI auto scaling.
- 6 min
- Includes a diagram
- Bedrock quotas are requests and tokens per minute per model and Region; throttles show as
InvocationThrottles. - Throttling reserves input tokens plus max_tokens; prompt cache reads do not count toward tokens-per-minute.
- Service tiers: Reserved, Priority, Standard (default), Flex.
What it is
GenAI throughput is measured in tokens, not just requests. One request may carry 200 tokens or 200,000, so capacity planning, quotas and scaling all have to think in tokens per minute.
On Amazon Bedrock you do not manage servers; you manage quotas and capacity options. On Amazon SageMaker AI you manage instances, so you also tune auto scaling.
How it works
Quotas and token-based capacity planning
On-demand Bedrock usage is limited per model and Region by requests per minute and tokens per minute. Excess requests get a ThrottlingException, counted by the InvocationThrottles metric.
Plan capacity from the prompt and completion pattern:
- Peak requests per minute times average input tokens and output tokens per request.
- Throttling reserves input tokens plus max_tokens at request time, so plan with your maxTokens setting, not only the actual output.
- Cache reads from prompt caching do not count toward the tokens-per-minute quota; cache writes do.
- Watch
EstimatedTPMQuotaUsage, but do not use it alone for capacity planning, because it is an approximation.
When the plan exceeds the default quota, request an increase through Service Quotas or choose a reserved capacity option.
Handling throttling and concurrency
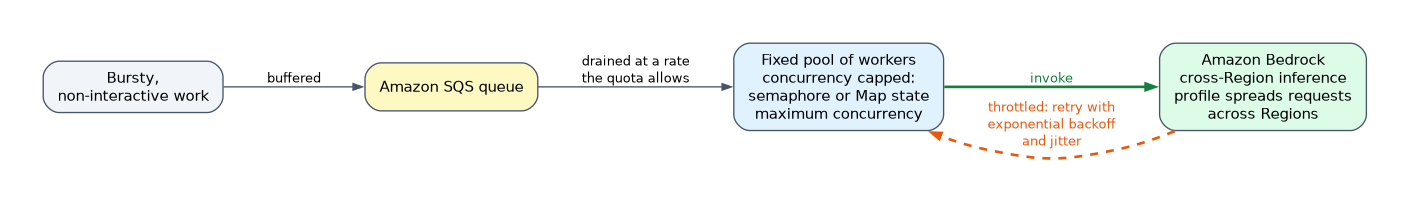
- Retry throttled calls with exponential backoff and jitter; the AWS SDKs do this by default.
- Put an SQS queue in front of the model for bursty, non-interactive work, and let a fixed pool of workers drain it at a rate the quota allows.
- Cap concurrent model invocations in the application, for example with a semaphore or the Step Functions Map state's maximum concurrency.
- Use cross-Region inference profiles (geographic or global) so Bedrock spreads requests across Regions, which raises available throughput during peaks.
Bedrock capacity options
| Option | Billing | Best for |
|---|---|---|
| On-demand, Standard tier | Per token | Everyday traffic; the default |
| Priority tier | Per token at a premium | Customer-facing, latency-sensitive requests that need prioritization without a reservation |
| Flex tier | Per token at a discount | Work that can wait, such as evaluations and summarization |
| Reserved tier | Fixed price per reserved tokens per minute, 1 or 3 month terms | Mission-critical steady traffic; overflow goes to Standard |
| Provisioned Throughput | Hourly per Model Unit, with no commitment, 1 month or 6 month terms | Guaranteed throughput for a base or custom model |
| Batch inference | Discounted per token for supported models | Large offline jobs with no real-time need |
A Model Unit (MU) delivers a set number of input and output tokens per minute for a specific model. Longer commitments lower the hourly price, but billing continues until you delete the Provisioned Throughput, so idle MUs are pure waste.
Provisioned Throughput is billed whether or not you use it. For spiky or low traffic, on-demand is cheaper. Right-size MUs from measured peak tokens per minute, not from a guess.
Batch inference strategies
Batch inference processes many prompts asynchronously.
- Write records as JSONL in Amazon S3, in InvokeModel or Converse format.
- Start a job with CreateModelInvocationJob, pointing to the input and an output S3 location.
- Get job state changes through Amazon EventBridge instead of polling.
- Read results from S3 when the job finishes.
Batch inference is not supported for provisioned models, and prompt caching does not apply to batch jobs. Group many small items into each record where the task allows, so fixed instructions are not repeated thousands of times.
Token processing optimization
- Shorter prompts and capped outputs mean more requests fit in the same tokens-per-minute quota.
- Batching several short items into one prompt (for example, classify 20 reviews and return JSON) cuts repeated instruction tokens.
- Streaming does not raise throughput, but it improves perceived speed; throughput comes from quota, capacity and token count.
Auto scaling on SageMaker AI
Self-hosted LLMs on SageMaker AI endpoints scale with Application Auto Scaling target tracking.
| Metric | Behavior | Use |
|---|---|---|
SageMakerVariantInvocationsPerInstance | Standard metric, emitted every minute | General models with short, uniform requests |
SageMakerVariantConcurrentRequestsPerModelHighResolution | High resolution, emitted every 10 seconds, counts in-flight requests until the last streamed token | LLMs with long, variable generation times |
SageMakerInferenceComponentConcurrentRequestsPerCopyHighResolution | Same idea per inference component copy | Several models sharing one endpoint through inference components |
Concurrency fits GenAI better than invocations per minute, because one long generation occupies the model far longer than a short one. The high-resolution metrics scale out faster; scale-in still happens at standard speed. Set cooldowns so the fleet does not flap.
How the exam asks about this
- "Summarize 2 million documents overnight at the lowest cost" -> Bedrock batch inference with JSONL input in S3.
- "Throttling during regional peaks with minimal changes" -> cross-Region inference profile plus retries with backoff.
- "A SageMaker AI LLM endpoint scales too slowly when long generations pile up" -> target tracking on the concurrent requests high-resolution metric.
Common mistakes
Buying Provisioned Throughput for unpredictable, low traffic. Hourly billing for idle capacity costs more than on-demand.
Scaling an LLM endpoint on CPU or invocations per minute. Neither reflects how many long generations are in flight; concurrency does.
Retrying throttled calls immediately in a tight loop. It makes throttling worse. Use backoff with jitter or a queue.
What to remember for the exam
- Bedrock quotas are requests and tokens per minute per model and Region; throttles show as
InvocationThrottles. - Throttling reserves input tokens plus max_tokens; prompt cache reads do not count toward tokens-per-minute.
- Service tiers: Reserved, Priority, Standard (default), Flex.
- Provisioned Throughput: Model Units, hourly, no commitment or 1 or 6 month terms.
- Batch inference: JSONL in S3, CreateModelInvocationJob, discounted, not for provisioned models.
- SageMaker AI LLM endpoints scale best on high-resolution concurrent request metrics.
Check yourself
Why is concurrency a better scaling signal than invocations per instance for an LLM endpoint?
Generation time varies widely, so in-flight requests show real load, and the high-resolution metric reacts every 10 seconds.
When is Provisioned Throughput the wrong choice?
For spiky or low traffic, because it is billed hourly per Model Unit even when idle.
What should replace synchronous calls for a large nightly document job?
A Bedrock batch inference job that reads JSONL from S3 and writes results back to S3 at a discounted price.
Topic 3 of 7 in Operational Efficiency and Optimization for GenAI Applications
Test yourself on Operational Efficiency and Optimization for GenAI Applications
The full AWS AIP-C01 question bank has 827 questions, with timed practice exams and an explanation for every answer.
This study guide is independent and is not affiliated with, endorsed by, or sponsored by AWS. Vendor names, certification names and exam codes are trademarks of their respective owners and are used for identification only.