AI Safety, Security, and Governance · Topic 1 of 7
Content Safety for Inputs and Outputs
Filter harmful prompts and responses with Bedrock Guardrails, add custom moderation with Step Functions and Lambda, and use text to SQL for exact answers.
- 6 min
- Includes a diagram
- Amazon Bedrock Guardrails filters both prompts and responses. Content filter categories are Hate, Insults, Sexual, Violence, Misconduct and Prompt Attack.
- Denied topics block subjects; word filters block exact words; sensitive information filters block or mask PII.
ApplyGuardrailchecks text without invoking a model, so guardrails can protect any model or any text.
What it is
Content safety stops harmful material from reaching a foundation model (FM) and stops harmful material from leaving it. Inputs can carry hate, violence, sexual content, insults, misconduct or attempts to steer the model. Outputs can contain the same, or confident answers the business cannot stand behind.
The managed tool for both directions is Amazon Bedrock Guardrails. Custom moderation with AWS Step Functions and AWS Lambda fills the gaps, and evaluations prove the filters work before and after release.
How it works
Amazon Bedrock Guardrails policies
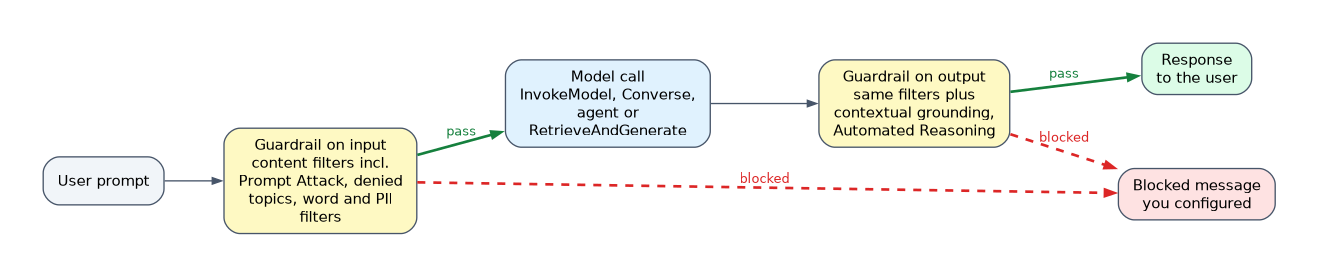 A guardrail is a reusable set of policies. You attach it to model calls (
InvokeModel, Converse and their streaming variants), to Bedrock Agents and to knowledge base RetrieveAndGenerate calls. The ApplyGuardrail API evaluates text without calling a model, so it also protects self-hosted or third-party models.
| Policy | What it catches | Typical use |
|---|---|---|
| Content filters | Hate, Insults, Sexual, Violence, Misconduct, plus Prompt Attack | General toxicity, set per category from NONE to HIGH strength |
| Denied topics | Subjects you define in plain language | A bank assistant that must not give investment advice |
| Word filters | Exact words and phrases, plus a managed profanity list | Competitor names, banned terms |
| Sensitive information filters | Built-in PII types and custom regex | Block or mask PII in prompts and responses |
| Contextual grounding checks | Responses not grounded in the source or not relevant to the query | RAG answers that invent facts |
| Automated Reasoning checks | Responses that break logical rules you define | Policy or eligibility answers that must follow written rules |
Filter strength and action are set separately for the input and the output. When a policy blocks content, the caller receives the blocked message you configured instead of the model text. The NONE action (detect mode) returns what was found without blocking, which is useful for tuning a new guardrail on live traffic.
Guardrails are versioned. Applications should reference a numbered version, not the working draft, so a policy edit does not change production behavior until you publish and switch versions.
Custom moderation workflows
Some rules cannot be expressed as guardrail policies: a customer tier that allows different content, a lookup against a blocklist in DynamoDB, or a human decision for borderline cases. Build those as a workflow.
- Lambda runs fast synchronous checks, such as length limits, allowed languages or calls to Amazon Comprehend
DetectToxicContent. - Step Functions chains checks, retries failures and branches on results. The callback pattern with a task token pauses the workflow until a human approves or rejects.
- Real-time validation keeps the synchronous path short. Slow or human checks belong on an asynchronous branch, not in the chat request path.
Use an Express workflow for high-volume, short moderation steps and a Standard workflow when a human review can take hours.
Proving output safety with evaluations
Filters need evidence. Amazon Bedrock model evaluations can score responses with an LLM as a judge using built-in responsible AI metrics such as Harmfulness, Stereotyping and Refusal. Run the same prompt dataset against the model with and without the guardrail to measure what the guardrail changes.
Amazon Comprehend DetectToxicContent returns a toxicity score and category labels for English text. It works as a lightweight classifier in a batch evaluation of logged outputs or as an extra check in a Lambda function.
Text to SQL for deterministic results
When the answer is a number in a database, such as an order total or a balance, a free text answer from the model is risky. The safer pattern has the model write a SQL query, and the database returns the exact value.
Validate the generated SQL before running it. Allow only SELECT, run it with a read-only database user and limit the tables it can touch. Amazon Bedrock Knowledge Bases can also connect to a structured data store such as Amazon Redshift and generate the query for you.
Common mistakes
Filtering only the output. Harmful or manipulative prompts still reach the model, cost tokens and can steer agent actions. Configure input filters as well as output filters.
Writing a custom classifier for standard categories. Hate, violence, sexual content and insults are built-in guardrail categories. A custom model adds cost and operational overhead for no gain.
Letting the model state database facts. A model summarizing a balance from memory or from a large prompt can be wrong. Text to SQL returns the stored value, so the answer is repeatable.
Pointing production at the draft guardrail. Editing the draft then changes live behavior with no review. Publish a version and reference it.
What to remember for the exam
- Amazon Bedrock Guardrails filters both prompts and responses. Content filter categories are Hate, Insults, Sexual, Violence, Misconduct and Prompt Attack.
- Denied topics block subjects; word filters block exact words; sensitive information filters block or mask PII.
ApplyGuardrailchecks text without invoking a model, so guardrails can protect any model or any text.- Step Functions plus Lambda builds custom moderation, and a task token pauses for human review.
- Bedrock model evaluations with an LLM as a judge measure Harmfulness, Stereotyping and Refusal.
- Text to SQL gives deterministic answers for structured data. Validate the query and run it read only.
Content blocked by a guardrail still appears as plain text in Amazon Bedrock model invocation logs if logging is on. Protect those logs as sensitive data.
Check yourself
A support chatbot must never discuss legal advice, but the model is otherwise fine. What is the least effort control?
Add a denied topic for legal advice to an Amazon Bedrock guardrail and attach it to the model calls.
How do you apply the same guardrail to a model hosted outside Amazon Bedrock?
Call the ApplyGuardrail API on the prompt and on the response, because it evaluates text without invoking a Bedrock model.
Why use text to SQL instead of putting a sales table in the prompt?
The database returns the exact stored values, so answers are deterministic and do not depend on the model reading numbers correctly.
Topic 1 of 7 in AI Safety, Security, and Governance
Test yourself on AI Safety, Security, and Governance
The full AWS AIP-C01 question bank has 827 questions, with timed practice exams and an explanation for every answer.
This study guide is independent and is not affiliated with, endorsed by, or sponsored by AWS. Vendor names, certification names and exam codes are trademarks of their respective owners and are used for identification only.